|
|
MODEL
SEISMIC
2026-10-15
Muse Spark Open — Meta's 816B open-weight model for coding and agents
Meta puts an 816B Muse model with a 1M-token context into open weights, sized to run on two Mac Studios.
What is it?
Muse Spark Open is an open-weight model from Meta Superintelligence Labs, released for coding and long agent tasks. Meta calls it the most capable US open-weight model to date — until now, the only open-weight Muse model was the 30B Muse Glimmer.
How does it work?
It's a mixture-of-experts transformer with 256 experts, 8 active per token, so only 42B of its 816B parameters work on each token. Reasoning effort can be set from low to xhigh, and Meta ships BF16 and NVFP4 builds for SGLang, vLLM, Transformers, MLX and llama.cpp.
Why does it matter?
A model this size usually needs a GPU server, but Meta says two M5 Ultra Mac Studios with 512 GB of unified memory each can hold the full model. It leads MCP-Atlas at 89.2 on Meta's own benchmarks — the first frontier-scale open-weight model you can run at home.
Who is it for?
Teams that self-host models, local-AI builders with large Apple Silicon machines, and agent developers who need a frontier open-weight base.
|
|
|
|
MODEL
MAJOR
2026-10-15
FLUX 3 Image Klein — Black Forest Labs' 5.6B open-weights image model
A small open-weights FLUX 3 model that makes, edits and combines images on a consumer GPU.
What is it?
FLUX 3 Image Klein brings Black Forest Labs' FLUX 3 image line to open weights in a 5.6B-parameter model. One model handles text-to-image, single-image edits and composition from up to 10 reference images, with native 4K output and bounding-box control.
How does it work?
Two checkpoints ship: a Klein Base for fine-tuning, and a step-distilled model that uses 16 steps with no guidance for fast generation. A Qwen3-VL-4B-Instruct model serves as the text encoder; the INT8 build fits on 8 GB of VRAM.
Why does it matter?
Open image models usually trade quality for size. Black Forest Labs claims this one ranks first among open-weights models in its internal tests while fitting on a gaming GPU, and companies with under $5M revenue can use it commercially for free.
Who is it for?
Image-pipeline builders, ComfyUI users, and fine-tuners who want a capable local model without server hardware.
|
|
|
|
MODEL
MAJOR
2026-10-15
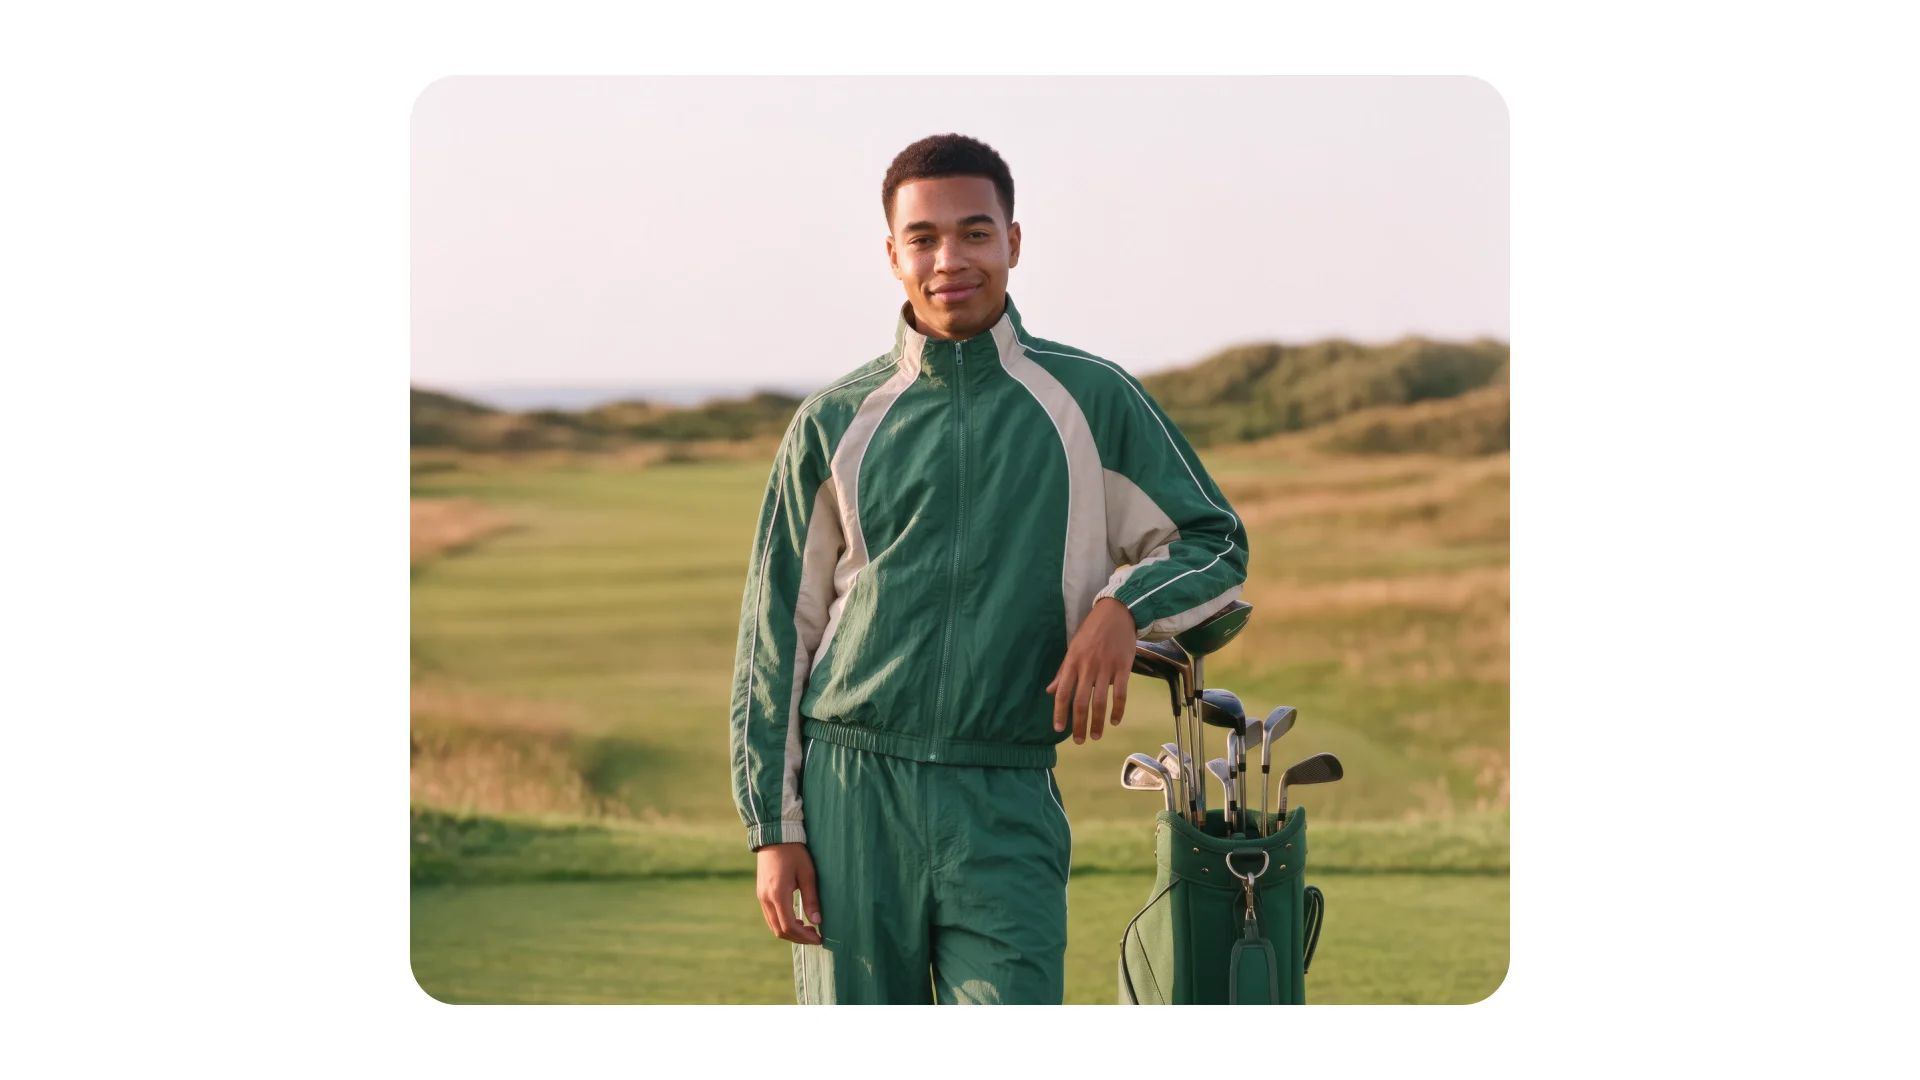
Krea 3 — Krea's image model built for fast, precise editing
An editing-first image model that keeps everything you did not ask to change, at 2K in under 8 seconds.
What is it?
Krea 3 is built around editing rather than first drafts. You ask for one change — new seating in a room photo — and it changes only that part while product labels, logos and the rest of the frame stay intact. Each edit can use up to six reference images.
How does it work?
Edits are generated at native 2K resolution. Krea's own timing data (Sep 24 – Oct 1, 2026, including queue time) puts Krea 3 under 8 seconds end-to-end, against 27 s for Nano Banana 2 and 90 s for GPT Image 2.
Why does it matter?
Speed and cost compound at scale: Krea prices 100,000 edits a month at $6,000. The model is also available through fal, Replicate, OpenRouter and others, so developers can drop it into existing pipelines without a new vendor contract.
Who is it for?
Designers, e-commerce teams and developers who edit product imagery at volume.
|
|
|
|
MODEL
MAJOR
2026-10-15
Timestral — Mistral's first open models for time-series forecasting
Mistral's tiny Timestral models forecast any time series zero-shot, from 10 ms on a CPU.
What is it?
Timestral is a family of four time-series foundation models from Mistral AI (5M, 28M, 123M and 209M parameters). They forecast future values of one or many related series — sales, sensor readings — without training on your data first, outputting 21 forecast quantiles per step.
How does it work?
Training is mostly on synthetic data. A technique Mistral calls Decoupled Horizon Forecasting keeps the full history in the sequence and adds learned forecast tokens; covariate-aware attention lets known-future signals (like a holiday calendar) flow only to targets, not the reverse.
Why does it matter?
The 5M model runs in 10 ms on an 8-thread CPU and the 28M model outscores the ~112M Chronos-2 on GIFT-Eval and TIME benchmarks — a rare case of a smaller model clearly beating a larger one in its own category.
Who is it for?
Data scientists and forecasting or ops teams who need zero-shot time-series predictions inside existing CPU-based data pipelines.
|
|

|
|
TOOL
NOTABLE
2026-10-15
Codex CLI 0.163.0 — steer mid-response and run read-only tools in parallel
You can now redirect Codex in the middle of a reply, and it runs independent read-only tools at the same time.
What is it?
Codex CLI 0.163.0's headline is mid-response steering: a follow-up message sent while the agent is still answering redirects it right away, and an interrupt now also stops active Code Mode cells. The /config panel is now searchable, with some settings applying immediately.
How does it work?
Independent read-only tool calls now run in parallel. A configurable leader key (Ctrl+X by default, set in /keymap), voice mute moved to F9, and a /daemon command restarts the managed background server.
Why does it matter?
Resuming a saved thread now restores its permissions and network approvals — old sessions no longer need re-approval. The network proxy also checks permissions before DNS lookups, closing a potential bypass.
Who is it for?
Developers who use the Codex terminal coding agent in day-to-day engineering work.
|
|
|
|
SECURITY
NOTABLE
2026-10-15
Anthropic gives METR employee-like access — evaluators can publish findings
Anthropic embeds an outside safety evaluator with near-internal access and no publication veto.
What is it?
Anthropic is giving a small team from METR — a nonprofit that evaluates frontier AI models — access comparable to its own risk assessment teams: company hardware, office space and internal tools. Anthropic also published three access tiers for outside evaluators, from narrow investigations it approves up to METR's top tier.
How does it work?
METR's six-person embedded team is siloed from other METR staff and works under enforceable agreements. Anthropic says it cannot veto publication but can require redactions only in predefined categories: customer data, privileged information and model architectures.
Why does it matter?
Most outside model evaluations depend on whatever access and terms a lab chooses to offer. Anthropic is arguing every frontier AI company should embed evaluators voluntarily, giving policymakers a concrete template to benchmark against.
Who is it for?
AI safety researchers and policymakers following how labs structure third-party oversight.
|
|
|
All releases at ai-tldr.dev
Simple explanations • No jargon • Updated daily
|
|