| View in browser: The Diff No. 005 |
| The Diff No. 005 Thursday, 8 October 2026 · AI dev news, only what is verified |
 |
Eight million little questions. One cheaper model. AlphaSense says one document-question feature makes 8 million calls a week. Its engineers tested 400 queries against the new Haiku. That is a more useful launch story than another giant benchmark chart. Elsewhere: Docker puts agents in YAML, a reverse-engineering tool asks for evidence, and a benchmark author discovers that his own labels were wrong. Cheap is useful. Verified is a separate question. |
IN THIS ISSUE | 01 🐇 The cheap model gets a real job Do not hand it the whole repository. Hand it one question. | 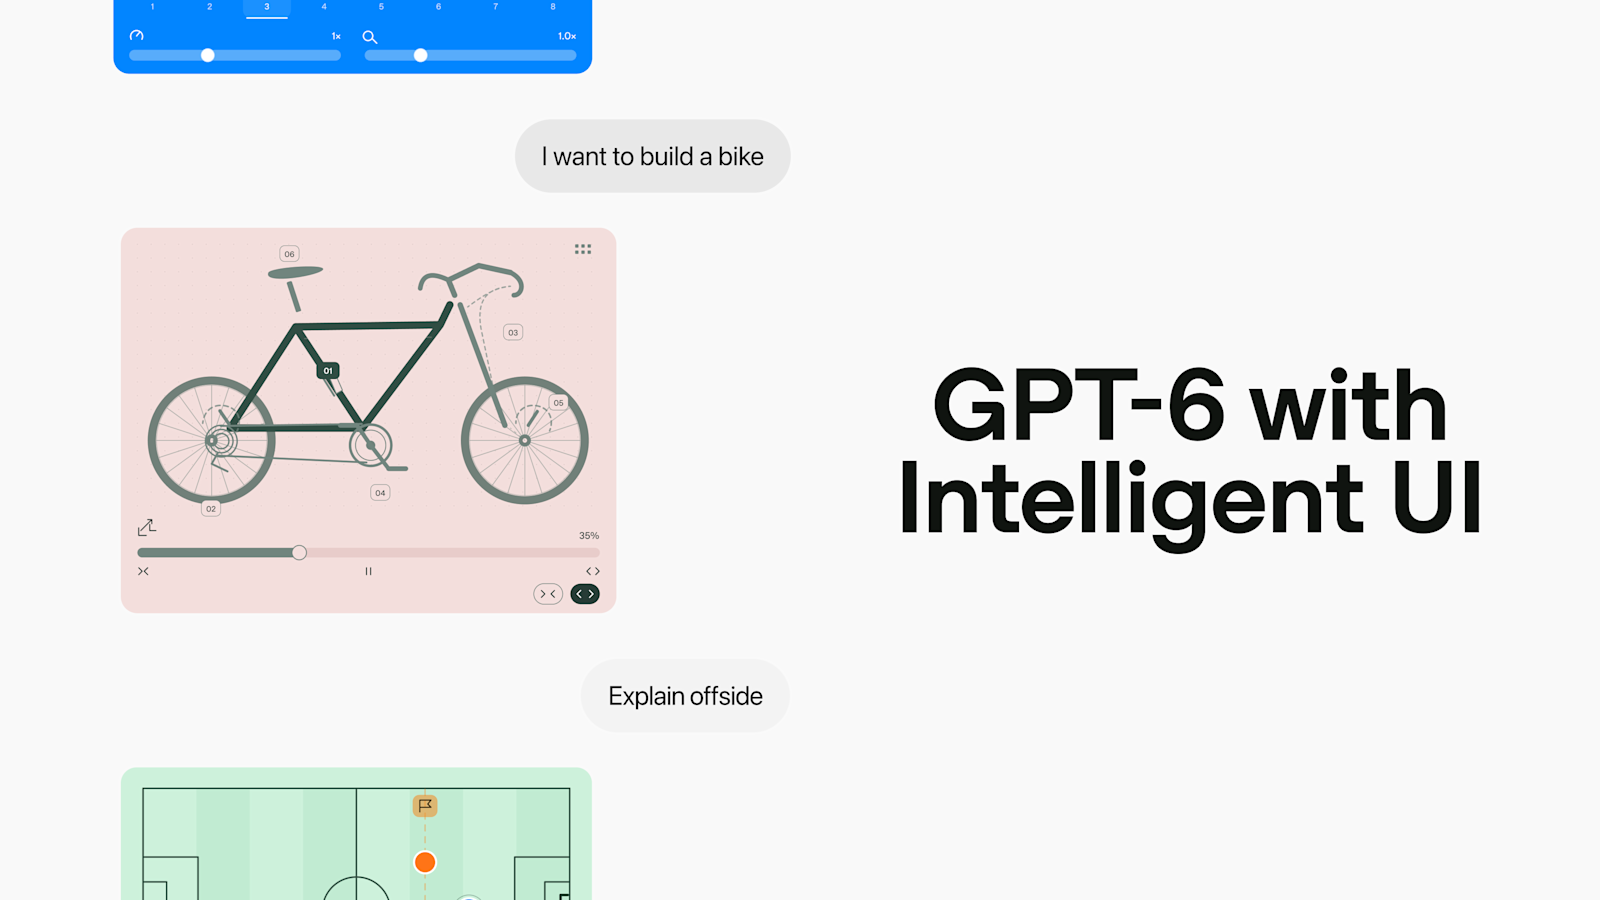 | 02 🧩 The answer grows buttons ChatGPT gets a UI compiler, not just a prettier paragraph. |  | 03 🐳 Put the agent in version control The config is YAML. The work still needs review. | | 04 🔬 Show me how that app works A binary inspection kit, not a magic clone button. | | 05 📨 Telegrams for expensive tokens Shorter text can still cost more. | | 06 🟢 His benchmark caught him first The model was right. The labels were wrong. |
|
🔥 VIRAL The loud ones on Hacker News. Numbers are a morning snapshot. | 01 HN: 723 points / 366 comments at 06:25 IDT · artwork: Anthropic 🐇 The cheap model gets a real jobDo not hand it the whole repository. Hand it one question. SCENE AlphaSense engineer Daniel Campos says Ask in Document makes about 8M production calls a week. On 400 queries, his team measured 0.84 for Haiku 5.5 against 0.76 for Haiku 4.5. The launch page does not define that score in the quote. Asana separately reports faster bug-triage and project-setup work. These are customer claims published by Anthropic, not our tests. THE THING Haiku 5.5 adds adjustable effort and targets summaries, database queries and narrow subagent work. Up to 100k prompt tokens, input/output cost $0.10/$0.50 per million; above that, $0.50/$2.50. Anthropic calls it around 75% cheaper on average, accounting for workload and tokenization. Its own Terminal-Bench score still trails Sonnet 5.5: 39.2% versus 70.6%. ✂️ STEAL IT Pick a repeated small job with an answer you can check: pull one revenue line, classify a bug, or summarize a diff. Compare error rate, wall-clock time and total bill with your current model. Keep the stronger model on the decisions. Try today VERDICT A bounded eval is worth doing. A cheaper token can become an expensive retry loop; long prompts use the higher rate. Vendor benchmarks do not settle your workload. Announcement + prices · HN discussion Tap one, then press send in the email that opens. Researched replies usually land within about 10 minutes. More like thisLess like thisDig deeperAlready knew it |
02 HN: 529 points / 278 comments at 06:25 IDT · artwork: OpenAI 🧩 The answer grows buttonsChatGPT gets a UI compiler, not just a prettier paragraph. SCENE OpenAI shows a seven-speed bicycle broken into tappable systems, then a Sunday roast turned into quantities and a cooking timeline. A user can ask for a bill splitter or calculator inside the conversation. These are announcement examples, not our hands-on session. THE THING The Oct 7 release brings GPT-6 and Intelligent UI to more ChatGPT users. OpenAI says it trained the model to compose native, streamable components; a compiler assembles the interface while the response arrives. This page describes ChatGPT. It does not announce a developer API for that component library. ✂️ STEAL IT For your next internal tool, ask what the user needs to change, compare or confirm. A short form or two-column comparison may beat a chat transcript. Keep a plain-text path for people who cannot use the interactive one. Watch VERDICT The interaction pattern is worth stealing. Do not plan a production integration around an API this announcement does not provide, or mistake a generated calculator for validated business logic. Official release · HN discussion Tap one, then press send in the email that opens. Researched replies usually land within about 10 minutes. More like thisLess like thisDig deeperAlready knew it |
03 HN: 190 points / 87 comments at 06:25 IDT · card: GitHub 🐳 Put the agent in version controlThe config is YAML. The work still needs review. SCENE Docker's README starts with a helpful root agent and a DuckDuckGo MCP tool in one YAML file. Run the file with docker agent run. The same README shows how to pull an agent from an OCI registry, so the team can share a configuration rather than another setup transcript. THE THING Docker Agent is a CLI plugin with multi-agent delegation, provider choice, MCP tools and retrieval options. Docker Desktop 4.63+ includes it; standalone releases are available. Cloud models need their own keys, while Docker Model Runner is an alternative for local models. We reviewed the docs, not an installed run. ✂️ STEAL IT Begin with one read-only task and a versioned YAML file. Review the model and every tool before pulling a shared agent configuration. The fact that an agent lives in a registry says nothing about what it is allowed to read or execute. Watch VERDICT Useful packaging, not automatic safety. A downloaded agent config can expose powerful tools and spend API money. Start with minimal permissions and an explicit budget. README + install · HN discussion Tap one, then press send in the email that opens. Researched replies usually land within about 10 minutes. More like thisLess like thisDig deeperAlready knew itTest it for me |
🔭 UNDER THE RADAR Quiet tools and field reports worth your time. | 04 REA · 383 stars on primary repo read · MIT · created April 14 🔬 Show me how that app worksA binary inspection kit, not a magic clone button. SCENE The REA README gives an example: ask an agent to understand search in Notes, show the evidence, then build something suited to your own project. The operator no longer has to copy decompiler output into a chat for every follow-up. This is the project's example, not a reconstruction we ran. THE THING morluto/rea connects CLI and MCP investigation to native analysis, managed binaries and selected web/Electron observation. Node.js 22+ is required. Host and provider support varies, including experimental Windows native analysis. Setup shows a plan and asks before changing agent registrations. Local analysis does not mean a configured cloud model receives no data. ✂️ STEAL IT Read the support matrix and setup dry-run first. Investigate a small app or binary you own, require evidence for each conclusion, and separate observation from permission to recreate anything. Do not start on a confidential commercial app. Watch VERDICT An interesting way to give an agent better evidence. It explicitly does not recover original source or automatically clone an app. Licensing, access rights and what reaches your model still matter. Primary repo + support · Project Tap one, then press send in the email that opens. Researched replies usually land within about 10 minutes. More like thisLess like thisDig deeperAlready knew itTest it for me |
05 Telegraph Test · 6 stars · Apache-2.0 · created Oct 4 📨 Telegrams for expensive tokensShorter text can still cost more. SCENE Travis42 compares a verbose record of the Royal Charter inquiry with a clipped cablese record. The repo bundles the records and billed-token ledgers, then asks other model families questions about the same facts. The headline is not a screenshot of a shorter paragraph: it is the provider's token meter. THE THING The author reports 40-49% fewer billed output tokens for lowercase cablese with thinking disabled where possible. But mandatory-reasoning gpt-5-mini made the compressed writes cost about twice as much. The blog also admits it has not tested a generic "write tersely" control. We read the data description; we did not reproduce the results. ✂️ STEAL IT Use an offline frozen-data replay before paying for a live run. Then compare a small machine-read summary against plain text with the same questions and token meter. Keep names, numbers and failure conditions intact. Watch VERDICT A testable idea for repetitive machine-read text, not a blanket 50% bill cut. Reasoning cost, tokenizer behavior and missing facts can cancel the gain. Never compress away the evidence a reviewer needs. Repo + frozen results · Author experiment Tap one, then press send in the email that opens. Researched replies usually land within about 10 minutes. More like thisLess like thisDig deeperAlready knew itTest it for me |
06 Denis Bardin · first-person benchmark report Oct 7 🟢 His benchmark caught him firstThe model was right. The labels were wrong. SCENE Denis Bardin built a benchmark for agents that say "all tests pass" when the log says otherwise. His first Gemini 2.5 Pro score was 0.69. Reading the failures, he found his own labels calling one Maven module a full suite and a killed build a partial test run. After rule-based label fixes, he reports 0.98. That is a scoring repair, not a smarter model. THE THING The task uses 48 synthetic session-log scenarios: stale tests, filtered runs, timeouts, all-skipped suites and failures hidden by a pipe. A report must get scope and outcome right, quote evidence and avoid claiming success. The linked Kaggle leaderboard could not be independently read, so its scores remain the author's report. ✂️ STEAL IT Before accepting "verified", ask: what ran, on which final code, with what exit and actual test result? Save the deciding log line. A green build is not a test suite; a zero exit from tail is not proof pytest passed. Try today VERDICT Add this check to one review today. The benchmark tests reporting on logs, not an autonomous agent's ability to fix software. Small differences at the top are not a reliable model ranking. Author report + benchmark link Tap one, then press send in the email that opens. Researched replies usually land within about 10 minutes. More like thisLess like thisDig deeperAlready knew it |
📊 THE ATTENTION GAP HN points, checked at 06:25 IDT. Attention, not quality. | Haiku 5.5 | | 723 | | Docker Agent | | 190 | | Intelligent UI | | 529 |
|
ALSO ON THE RADAR Lean checked what? A new preprint argues that a checked formal proof need not faithfully translate the original English argument. Its OpenAI Navier-Stokes examples are a criticism to inspect, not proof that every announced result is wrong. Preprint → |
🗂️ THE BORING STUFF Oct 7 · Haiku on AWS. AWS announces availability on Bedrock and Claude Platform on AWS; its performance descriptions are attributed to Anthropic. Release → Oct 7 · Sonnet cache reads. Anthropic halves Sonnet 5.5 cache-read pricing to $0.10 per million tokens. Its roughly 20% agent-work saving is a workload estimate. Pricing → Oct 7 · Glyph Cluster stealth. Vercel offers the model during its stealth period to eligible Pro/Enterprise teams with purchased credits. No ZDR; prompts and responses may be used for training. Do not use private code to test it. Terms → Primary sources, checked this morning. No paid model calls made. |
🧪 ONE THING TO TRY TONIGHT Make green earn its name. Take the last agent task you merged. Find the final edit and the first test run after it. If there is no run, the correct status is unverified. |
What this issue could not see. HN, GitHub, official pages and selected author reports were read; projects were not run. Reddit RSS returned 403 and date-bounded searches were empty. X mirror returned 451 with no usable search results. Bluesky and Product Hunt were blocked; LinkedIn was a login wall. Lobsters and dev.to were sampled. YouTube searches returned old or unrelated videos, so no launch-day video is recommended rather than dressing up a stale one. |
|
| Images: Anthropic, OpenAI and GitHub repository card. Source images are credited in each report. |
|