| View in browser: The Diff No. 004 |
| The Diff No. 004 Wednesday, 7 October 2026 · AI dev news, only what is verified |
 |
The trillion-parameter cat has a bill. Bijan Bowen runs Mistral Large 4 through a browser OS, games and a watch site. His reported bill: about $47. The results are mixed. The launch-day benchmark charts did not show that part. Meanwhile, a tiny decision pipeline finds a Kubernetes fault without a chatty agent. A 98-star app keeps Claude working after the laptop shuts. One developer notices his arms hurt less. Big models make headlines. Small changes make a working day. |
IN THIS ISSUE | 01 🐈 $47 to meet le Chonk The first test has more texture than the launch chart. |  | 02 🔧 AI designs the thing running AI An FPGA, not a tape-out. Still worth opening. |  | 03 🧲 One search box, four senses Text, pictures, audio and video share the same space. | | 04 🚨 The pod says 16Mi. YAML says 256Mi. The collector does the detective work. Jev chooses. | 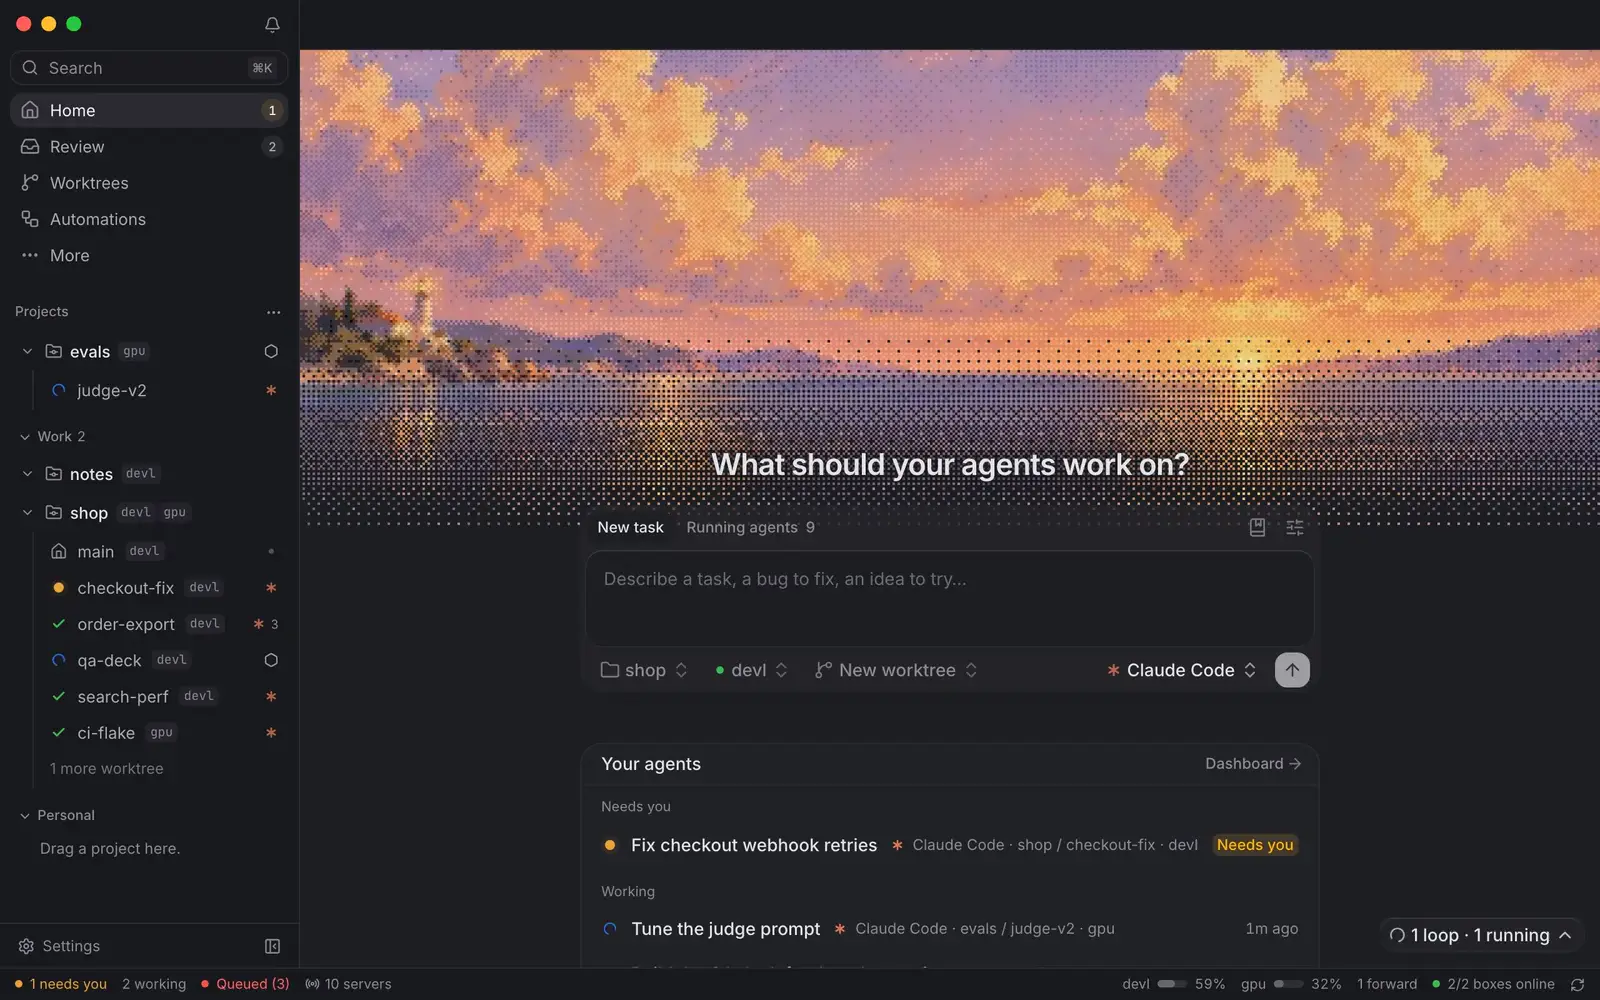 | 05 ⚓ Close the laptop. Keep the agent. A small harbour for your own dev boxes. | | 06 🎹 Less code. Less wrist gymnastics. One developer's benefit nobody put on a benchmark. |
|
🔥 VIRAL The loud ones on Hacker News. Numbers are a morning snapshot. | 01 HN: 1,623 points / 973 comments at 06:26 IDT 🐈 $47 to meet le ChonkThe first test has more texture than the launch chart. SCENE Bijan Bowen tests a browser OS and several games through Mistral Vibe. The OS can install little apps inside itself; the subway shooter initially fails to fire. His transcript ends with a roughly $47 total and no single result that blew him away. This is his test, not ours. THE THING Mistral Large 4 is a multimodal preview API: Mistral says 1T parameters, 49B active. Weights are promised by the end of October, not available for self-hosting today. Its coding and security benchmark results are vendor claims. ✂️ STEAL IT Before switching a coding agent, save one small task and its tests as a repeatable comparison. Run both models with the same harness and budget cap. Count fixes, time and the final bill, not just the screenshot. Watch VERDICT A useful new option, not a reason to replace your daily model on launch day. Long, high-effort tasks can erase a cheap token price; the preview may change. Mistral announcement · Bowen test + transcript · HN discussion Tap one, then press send in the email that opens. Researched replies usually land within about 10 minutes. More like thisLess like thisDig deeperAlready knew it |
02 Image: openTPU author · HN: 250 points / 308 comments · GitHub: 247 stars 🔧 AI designs the thing running AIAn FPGA, not a tape-out. Still worth opening. SCENE The openTPU author shows LFM2.5-230M chatting on a Kintex-7 PCIe card with a utilization monitor beside it. The README reports 82.1 tokens/s wall-clock for one 4-bit configuration and says the card matches its simulator token for token. Those are the author's measurements, not an independent hardware test. THE THING openTPU puts SystemVerilog RTL, an ISA simulator, compiler and host software in one Apache-2.0 repo, created September 24. The claim is AI-assisted accelerator design running on an FPGA. It is not a newly fabricated chip. ✂️ STEAL IT Read opentpu/isasim.py, then trace one instruction into the RTL and the test that checks it. This is an accelerator anatomy lesson before it is a purchasing decision. Watch VERDICT The readable full stack is the attraction. FPGA-specific build requirements and unreplicated performance numbers make it a learning project, not a GPU replacement. README + measurements · HN discussion Tap one, then press send in the email that opens. Researched replies usually land within about 10 minutes. More like thisLess like thisDig deeperAlready knew it |
03 HN: 244 points / 31 comments · artwork: Google 🧲 One search box, four sensesText, pictures, audio and video share the same space. SCENE Google's AI Edge team ships two demos: search local media and find a moment in a video. Instead of captioning every frame and transcribing every clip first, the model embeds the different inputs in a shared space. These are vendor demos; we have not run them. THE THING EmbeddingGemma 2 is Apache-2.0 and modular: Google's developer guide lists 270M parameters for text/code and 740M for all modalities, with 768-dimensional embeddings. It is a retrieval model, not a text generator. ✂️ STEAL IT In a throwaway environment, follow Google's guide: pip install -U "sentence-transformers[image,audio,video]" transformers, then load SentenceTransformer("google/embeddinggemma-2"). Start with ten known query/document pairs before indexing the world. Try today VERDICT A small local retrieval test is a better first step than rewriting RAG. Re-embedding an existing index is real work; modality support and memory still need checking on your hardware. Announcement · Developer guide · HN discussion Tap one, then press send in the email that opens. Researched replies usually land within about 10 minutes. More like thisLess like thisDig deeperAlready knew itTest it for me |
🔭 UNDER THE RADAR Quiet tools and field reports worth your time. | 04 Diagram: SREGym authors · HN: 10 points / 2 comments · study published Oct 6 🚨 The pod says 16Mi. YAML says 256Mi.The collector does the detective work. Jev chooses. SCENE Yiming Su and coauthors investigate a SREGym-Lite fault: nginx-thrift pods keep running out of memory. The Deployment says 256Mi; the live Pod has 16Mi. Their collector spots the mismatch and a matching admission webhook. Jev picks the component and supporting evidence. No LLM agent writes commands. THE THING The authors' Jev-driven diagnosis pipeline passes 80 of 105 attempts across 21 faults, with a 14.6-second median. All five attempts fail on each of five faults. A GPT-6-Astra rubric judges the diagnoses; this is a lab cohort, not production incident resolution. ✂️ STEAL IT Ask your existing incident collector to emit a compact table: component, symptom, live value, desired value, evidence ID. Test whether a fixed-choice router selects the right component from that evidence. Keep command execution separate. Watch VERDICT The valuable trick is structured evidence before model selection. A fast decider cannot discover a root cause your collector never represented; the authors show that failure boundary. Study + failure analysis · HN thread Tap one, then press send in the email that opens. Researched replies usually land within about 10 minutes. More like thisLess like thisDig deeperAlready knew it |
05 98 GitHub stars · created Oct 2 · project screenshot ⚓ Close the laptop. Keep the agent.A small harbour for your own dev boxes. SCENE Sean Brydon's Berth demo starts a task by choosing a project, a box and Claude Code. It creates a worktree on that box and shows the agent's edits as diffs. The agent runs there, so closing the laptop need not kill the task. This is the project's demo, not our live run. THE THING Berth is MIT-licensed: a Mac app, a CLI and a daemon for your own Linux or Mac boxes. The install docs require git, tmux and normally a Tailscale address. An open issue asks for Linear integration; do not assume your team workflow is already covered. ✂️ STEAL IT Read the install page and the daemon's integration changes first. Use a disposable repo on an existing dev box for one task. The installer creates a user service and agent hooks, so do not treat it as a harmless UI download. Watch VERDICT Good fit for a spare dev box, less so for a locked-down work laptop. It is young; pairing fixes are still arriving, and we have not tested reconnection or isolation. Project · Repo + issues · Install + side effects Tap one, then press send in the email that opens. Researched replies usually land within about 10 minutes. More like thisLess like thisDig deeperAlready knew itTest it for me |
06 HN: 51 points / 28 comments · first-person post Oct 5 🎹 Less code. Less wrist gymnastics.One developer's benefit nobody put on a benchmark. SCENE Vaughan Hilts sits down at the piano and notices little of his old arm pain. Mechanical refactors and feature work increasingly become prompts plus manual refinement. He types more English and fewer modifier-key contortions. He also has more meetings and a more senior role, so he does not claim the model caused it. THE THING A first-person account of changing the physical shape of coding work. Not a clinical study, not a cure, and not evidence to ignore pain. The useful detail is which keyboard motions disappeared. ✂️ STEAL IT For one afternoon, hand a mechanical refactor to an agent and keep review in your hands. Notice what changed in typing, fatigue and breaks. If pain persists, get appropriate care rather than a new model subscription. Watch VERDICT An honest anecdote worth noticing, not a health claim worth generalizing. Less typing can still mean more sedentary time or more review fatigue. Hilts' account · HN discussion Tap one, then press send in the email that opens. Researched replies usually land within about 10 minutes. More like thisLess like thisDig deeperAlready knew it |
📊 THE ATTENTION GAP GitHub stars, checked at 06:26-06:27 IDT. Popularity, not quality. |
ALSO ON THE RADAR A 300ms benchmark. matklad sizes microbenchmarks to about 300ms: long enough to see, short enough to repeat. His rule of thumb, not a universal measurement standard. Read → Backprop is not replaced. Dust explores activation perturbations for transformer pretraining. Its authors explicitly do not claim enough compute efficiency to replace backprop today. Paper → |
📺 VIDEO OF THE DAY  Mistral Is BACK: the bill at the end matters Bijan Bowen · 8,196 views · about 3 hours old at 06:27 IDT · thumbnail: YouTube Highest views per age among the launch-day videos returned in our Mistral search, not a claim about all YouTube. We read the transcript; we did not visually watch the whole 38-minute video. He reports UI successes, broken game mechanics, a vision-input problem and about $47 total. His release-date and price remarks are not our authority: the Mistral announcement says weights by the end of October. Watch on YouTube → | 🗂️ THE BORING STUFF Oct 6 · OpenAI Decisions beta. The docs say only gpt-6-luna is supported at POST /v1/decisions. It returns predicates, choices or scores; use Responses for generated JSON or explanations. Docs → Oct 6 · Polars 2.0. Streaming and out-of-core are the default. The release encourages collect_schema() for early agent feedback and links a migration guide. Its SQL speed comparisons are vendor-run. Release → Oct 6 · EmbeddingGemma 2. Apache-2.0 applies to this release. The earlier text-only EmbeddingGemma docs are not the new multimodal model's spec. Guide → Primary sources. Pricing and performance not independently tested. |
🧪 ONE THING TO TRY TONIGHT Make the evidence boring. Take one old incident and turn its logs into component/symptom/evidence rows. See whether your model picks the same root cause before giving it another tool. |
What this issue could not see. HN, primary docs, repos and selected first-person reports were read. Reddit returned 403; X returned an access queue, so neither supplies this issue's viral ranking. Bluesky was blocked. Product Hunt and Lobsters were sampled; LinkedIn public search was thin and supplied no selected item. Projects were reviewed from source and docs, not run. |
|
| Images: Mistral, openTPU, Google, SREGym, Berth and YouTube. Source images are credited in each report. |
|