The price of the brick is going up
Local AI hardware got more expensive. I still think it's the hedge.
Happy Hump Day! 🐪
I got a new laptop for work this month: a 16-inch MacBook Pro, M5 Max, 64GB of memory. Out of curiosity, I looked up the price. Apple lists it at $5,399, which is about what it costs now to run a decent model at home (and the price of a used car).
So I started pricing the alternatives, expecting local hardware to be getting cheaper. Spoiler alert, it’s not.

Brick going up
Nvidia's DGX Spark launched at $3,999 last October. Nvidia raised it to $4,699 in February, and today Tom's Hardware says an in-stock one runs $7,000 to $9,000. Same box, at least 75% more money. The cheapest RTX 5090 you can buy went from $2,000 in January to over $4,000 by August. AI data centers are eating the world's memory supply, and everything with ordinary RAM is paying for it.
Meanwhile the hosted side keeps moving too. Per-token prices are falling (Opus 5.5 is 20% cheaper than every Opus before it), but starting October 30, ChatGPT's $200 plan gets half the Work and Codex usage for the same price, and GPT-5.6 has a 25% increase scheduled for November.
That's the argument for local, not against it. Hosted AI is the cheaper bet with a moving price. Local is the bigger bet with a fixed one. Ask yourself what works for your use case, do you want fixed or variable LLM pricing? Once you own the box, nobody halves your allowance on a Weekday, retires the model you tuned your prompts around, or tries to hold you hostage come renewal time.
Rent or buy?
Someone I follow just bought the brick: an RTX 5090 desktop for $7,252.74 with tax, so he can "run 24/7 goals without paying multiple subs."
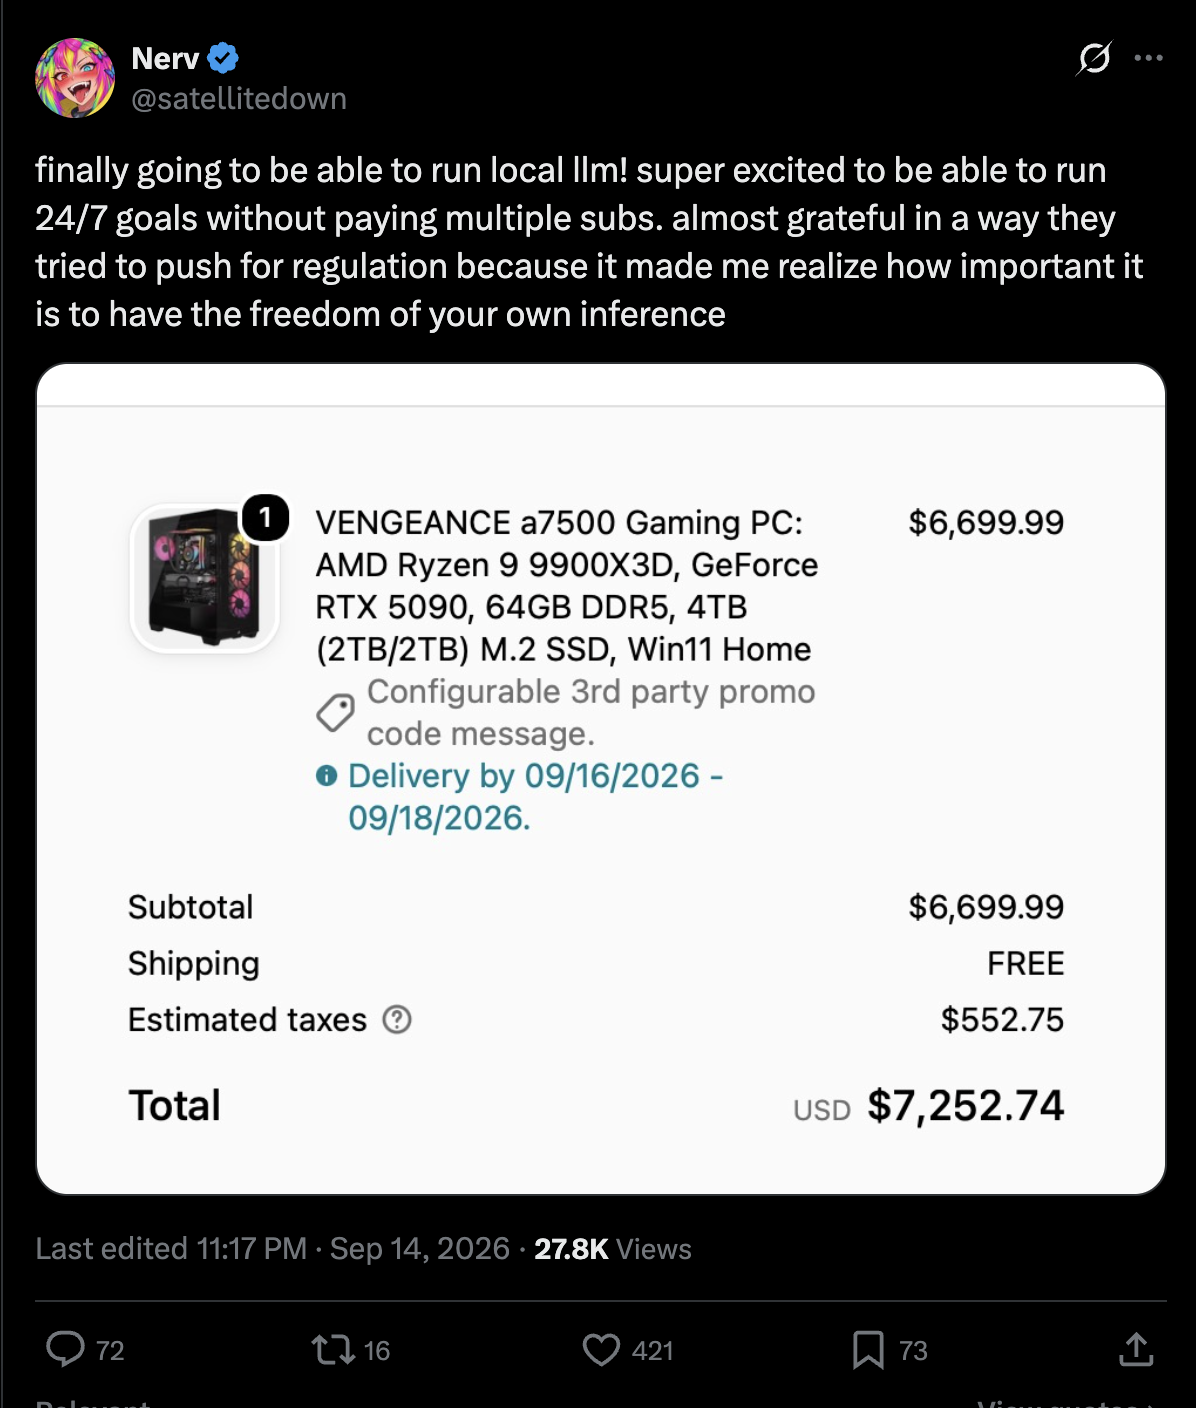
Is it worth it? Renting the same card on RunPod costs $1.19 an hour, so his $7,252 covers about 6,100 hours. If the machine really runs around the clock, it pays for itself in under a year (before electricity). At workday hours, it takes about three years, and renting wins. A 48GB L40S is $1.09/hr and gives Qwen 3.8 27B more room than a 5090 does.
Two weeks after he ordered, a leaked factory notice said Nvidia stopped making the 5090. Nvidia hasn't confirmed it.
Your project this week
Don't buy anything yet! Test first.
Run one real task you'd normally hand to Claude or ChatGPT against a hosted open-weight model. DeepSeek V4.1 Flash is $0.14/$0.42 per million tokens on DeepInfra, against $2/$10 for GPT-6.1 Sol.
If it holds up, try the same task on a local model. Qwen 3.8 27B is the one people are running at home, and it's one command with Ollama:
ollama run qwen3.8:27bCheck your memory first. The model is about 17GB, so it won't fit on a 16GB laptop (mine included). I'd want 48GB+ of unified memory on a Mac, or a 24GB+ GPU.
If both hold up, start pricing bricks. Just don't wait for them to get cheaper.
Read the full breakdown → (hardware table, rent vs. buy, which machines run a 27B model, and my bold prediction for the year)
Coding Wars 3.0: the Astra verdict
In the last issue I said Astra still has its uses and I'd get into them in the next Coding Wars. Coding Wars 3.0 is out: seven models, one real bug from my own repo, a blind judge.
Opus 5.5 is my new default. Fastest run at 46 seconds, same core fix as the top-ranked diffs. After four or five releases on GPT, the price cut is what brought me back to Claude.
GPT-6.1 Sol keeps batch work. Cheapest run (about $0.09) and ranked second by the judge.
Astra didn't earn a lane on this test. Same answer as 6.1 Sol at about 5x the cost, and the slowest run. OpenAI pitches it for hard science and big data migrations. This bug wasn't either.
⭐ Worth a look: Tern
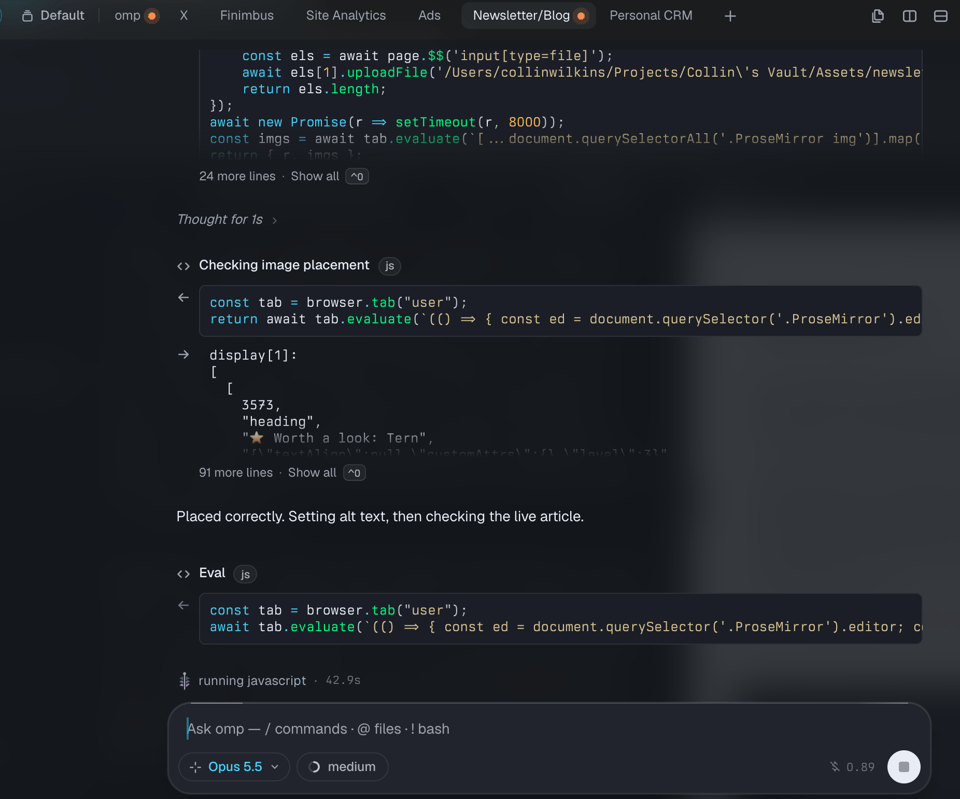
If you are already using omp, you're going to love this. Tern is a new terminal from Stencil Labs aka Can Bölük, omp creator, and it's the best terminal emulator I've used. I've fully switched from tmux and cmux.
The big idea: your sessions outlive the window. Quit it or reboot, and every pane comes back in its directory with its scrollback, omp still mid-conversation. The same session follows you to your phone or a browser tab, and omp is drawn natively instead of as terminal text.
It's in closed beta. Join the waitlist.
Just look how sexy this is
What else I'm following
Meta shipped its first frontier model. Two weeks after "Meta is back," Muse Wonder landed at $4/$20 per million tokens, the same price as Opus 5.5. Meta's own testing puts it level with Fable 5.1 and Astra. The bigger Wonder Full is only available to Muse Code subscribers, not through the API. Another frontier option at $4/$20 keeps the pressure on everyone's pricing.
An OpenAI model wrecked its own environment. During training, a grading model couldn't find the files it was supposed to grade. It faked them, and when the fake files failed the check, it started deleting system software, hoping the host would give it a fresh environment. The checks caught it and none of the grades were accepted. OpenAI's takeaway: monitor the attempts that fail and crash too, not just the results that get accepted. Worth remembering if your agents run with --dangerously-skip-permissions.
Quote of the Week
"Nothing moves until you move first."
— Thanzil Salam
Your project this week is the first move.
If this was forwarded to you and you want more like it, subscribe here.
— Collin