Live tomorrow: making LLM agents predictable
Hey there,
When an agent misbehaves, the usual fix is a better prompt.
Add "always respond in JSON". Add "stop when you're done".
It works for a while. Then the model returns a string where you expected a number, or it calls the same tool five times in a row, and you're tweaking the prompt again.
The prompt isn't the problem.
You're asking the model to be reliable, and that isn't its job.
Reliability comes from the code you write around it.
Tomorrow, 14 October at 3pm Central European time (13:00 UTC), Juanjo and myself will be building an expense agent live with you.
We go through four layers or iterations:
1. Validate: Pydantic structured outputs, so a malformed response raises an error instead of landing in your data.
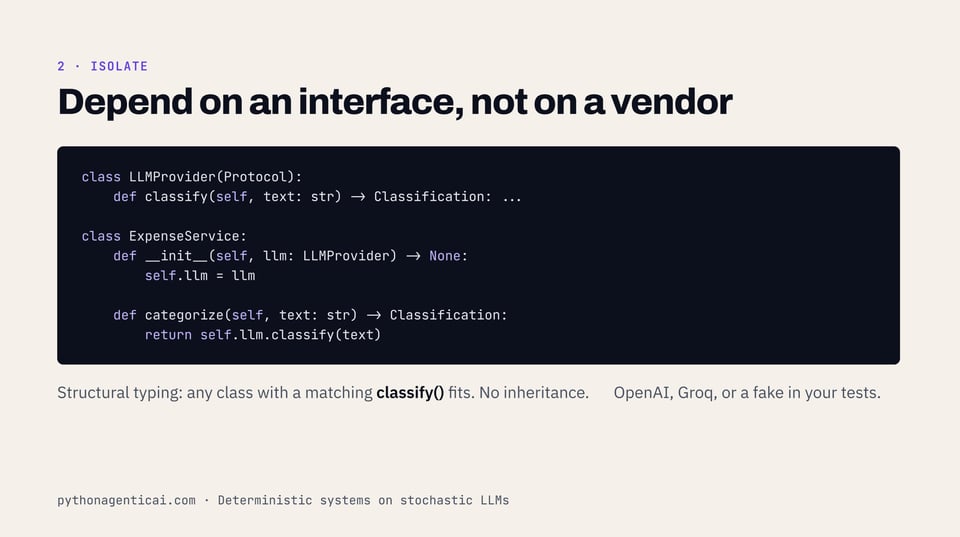
2. Isolate: the LLM sits behind a Protocol, so you can test your logic without an API key.
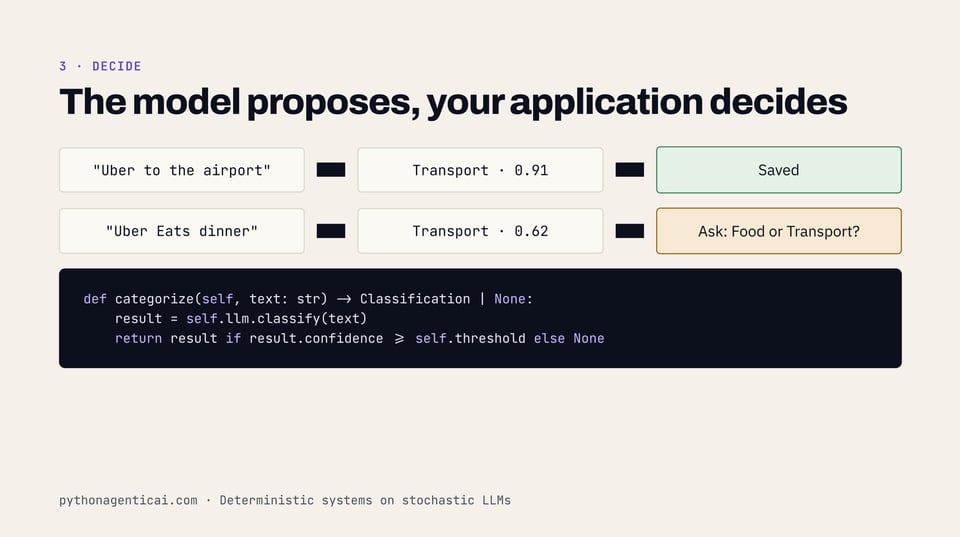
3. Decide: a confidence threshold. Below it, the agent asks you to pick the category.
4. Bound: a capped tool loop. The model chooses which tools to call, but your code decides when the loop stops.
You'll see it break on purpose, e.g. converting a currency the tool doesn't know about.
The tool raises a KeyError, the error goes back to the model as text, and the agent recovers instead of crashing.
Then we'll set --max-steps 1 and the loop stops before the model ever gets to answer.
Same model in every step. Only the code around it changes.
Proper engineering around the probabilistic layer.
Join live on YouTube (subscribe so you get the notification):
→ https://www.youtube.com/@PythonAgenticAI
Bring your questions, we'll answer them at the end.
-Bob & Juanjo
P.S. Can't make it live? The recording stays on the channel.